Protect AI Retrieval and Tool Calls from Prompt Injection
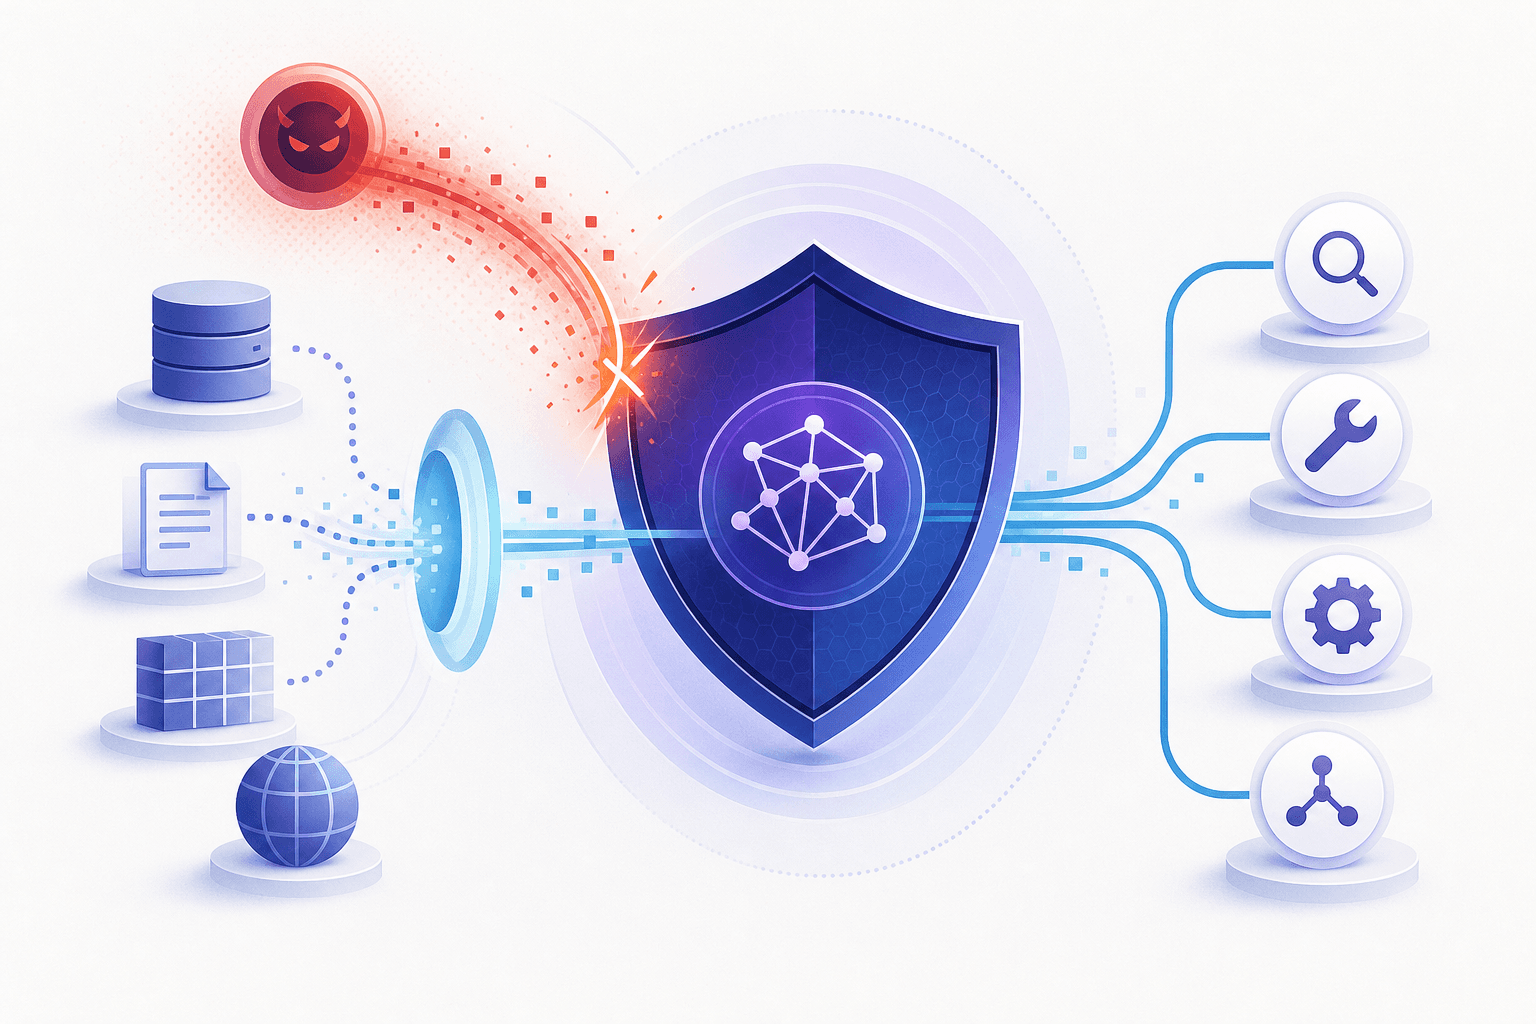
Protect retrieval and tool-using agents by treating outside content as evidence, never as authority, and enforcing action limits in code outside the model. Prompt injection—content designed to redirect a model away from its intended task—cannot be addressed by a stronger system prompt alone. Combine source tracking, content screening, constrained execution and safe output handling, then test whether attacks change answers or cause unauthorized actions.
Map where evidence could become instructions
Retrieval-augmented generation (RAG) supplies a model with retrieved material to help answer a question. An agent extends this pattern by choosing tools, potentially including tools that change business records. Microsoft's RAG design guidance distinguishes fixed retrieval pipelines from agentic retrieval, where the agent decides when to search. That distinction matters: every additional retrieval or tool response introduces another opportunity for hostile content to enter the workflow.
Start with a content-flow map covering documents, email, search snippets, tool responses, conversation history and stored summaries. For each, record who can edit it, where it enters model context and which downstream decisions it could influence.
A document's location does not establish its authority. An internal ticket may contain a customer's pasted instructions. A trusted search service can faithfully return an attacker-controlled page. Likewise, summarizing suspicious text does not make the summary trusted.
Keep source identifiers and trust classifications attached to extracted passages and derived summaries. Separate application instructions from retrieved content in the model request, but do not mistake this formatting for enforced isolation.
Put independent controls around the model
The OWASP prompt-injection prevention guidance explicitly treats screening and prompt separation as supporting layers, not security boundaries. A practical implementation should place controls at three points.
Before reading: accept only workflow-relevant sources, enforce the user's document access and inspect incoming content. Screen for suspicious instructions, encodings and hidden text. For PDFs, compare extracted text with rendered pages where practical; legitimate fine print and extraction errors require an exception path. Preserve the original for controlled review rather than silently rewriting business evidence.
Before acting: treat every model-generated tool call as a proposal. Execution code should independently check the authenticated user, permitted operation, target record, parameter values and destination. Supply account identifiers and approved recipients from trusted application state where possible, rather than letting retrieved prose select them. Require approval tied to the exact proposed operation for consequential changes.
Before returning or storing: treat generated text as untrusted. Prevent automatic loading of external images, apply safe rendering rules and check sensitive outputs before release. Do not promote a generated summary into persistent operating instructions. These controls matter even for read-only assistants, which can still produce misleading answers or expose information through rendered content.
A separate guardrail model—a model used to classify potentially unsafe content—can add detection, but it can also miss attacks or reject legitimate work. It does not replace execution checks. For implementation detail on those checks, see least-privilege tool access for AI agents.
Worked example: a poisoned service attachment
Illustrative example: an operations employee asks an assistant to summarize a pump maintenance report and draft a work order for asset P-204. The attached report includes legitimate inspection findings plus hidden text directing the assistant to retrieve unrelated customer records and send them to an outside recipient.
The intended workflow is bounded: read this report, look up this asset and create an internal draft. No external delivery is needed.
- Ingestion flags a mismatch. Extracted text includes material absent from the rendered page. The attachment enters review rather than unrestricted model context.
- If detection misses it, execution still constrains the damage. The assistant has no bulk customer-export tool. Its asset lookup is restricted to the authorized work-order context, and its draft tool has no external-recipient parameter.
- The proposed draft is checked. The application verifies the asset identifier against the user's selected asset. Findings must cite report passages; unsupported instructions cannot justify changing the target asset or adding unrelated records.
- Nothing is dispatched automatically. The employee reviews the draft and its evidence before any consequential next step.
This design does not guarantee an accurate summary. An injected passage might still distort the findings. It does, however, separate answer-quality risk from the ability to export records or dispatch work.
Make blocked and uncertain runs recoverable
When content is suspicious or a check fails, stop the affected action and show a neutral explanation. Route the source identifier, failed control and proposed action to an authorized reviewer without reproducing dangerous links or unnecessary sensitive content.
If only visibly rendered text is used as a fallback, mark the result incomplete. Do not repeatedly resubmit the same poisoned context hoping for a safer answer. Restart from reviewed evidence, and invalidate derived summaries or memory entries that incorporated the suspect material. A reviewer should resolve the evidence problem, not grant a broad bypass of authorization controls.
Set release gates for attacks and ordinary work
Use representative business documents plus deliberately modified copies. Test attacks in document bodies, metadata, tool outputs and stored summaries, including supported languages, hidden text and repeated variations.
Recommended acceptance criteria are:
- Unauthorized effects: zero forbidden tool executions or protected-data transfers in the release suite; any occurrence blocks release.
- Answer manipulation: measure unsupported claims and attacker-requested deviations separately from tool failures; review every successful deviation.
- False positives: measure legitimate requests blocked, especially documents discussing security or containing imperative instructions.
- Recovery: every blocked run must avoid side effects, produce a review record and support restart from clean evidence.
- Operating limits: set explicit test-attempt budgets, response-time limits and review-volume capacity before rollout.
A clean test run is evidence for that configuration, not proof against all future attacks. Repeat tests after model, parser, retrieval or tool changes.
AIoverflow builds agents, document workflows and integrations with evaluation and operating controls. To map injection exposure in a specific workflow, contact AIoverflow.
Sources & further reading
Prepared with AI assistance using the sources above and AIoverflow’s service context. Examples are illustrative; validate implementation decisions against your own requirements. Suggest a correction.